AI Quality & Evaluation
Review AI responses for factual accuracy, instruction-following, consistency, usefulness, and failure points.
LISA MARIE KOCIAN
Domain SME: E-Commerce & Digital Product Operations
I evaluate AI responses and digital products for accuracy, reliability, and usability. My work combines quality assurance, e-commerce operations, and human-centered evaluation to identify problems, understand why they happen, and help make technology more dependable.
Open to opportunities in AI Quality Assurance, LLM Evaluation, Content Quality, and AI Product Testing.
PROFESSIONAL FOCUS
Where technical review, digital operations, and practical judgment meet.
Review AI responses for factual accuracy, instruction-following, consistency, usefulness, and failure points.
Experience with Python, Java, PHP, C++, and Ruby, combining programming knowledge with technical troubleshooting, software QA, and practical problem-solving.
Test website workflows, navigation, product data, responsive layouts, and customer-facing experiences.
Combine web development, business operations, troubleshooting, content management, and documented reviews.
FEATURED WORK
Examples of what I built, reviewed, and learned along the way.
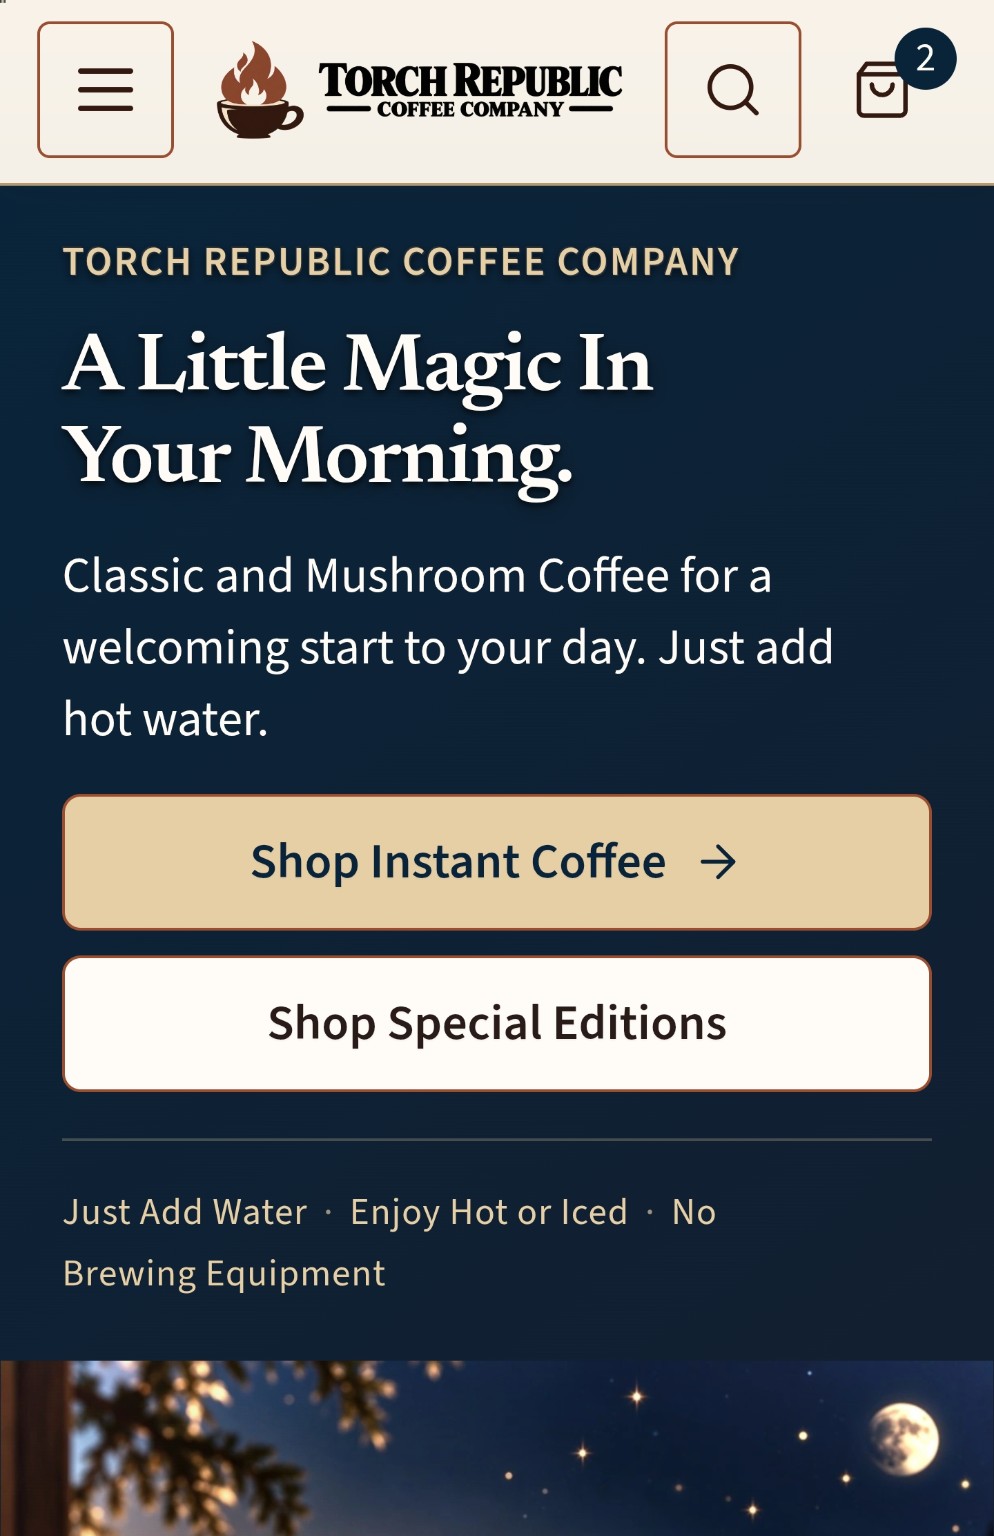
An independently developed React-based commerce experience connecting boutique coffee merchandising, Shopify product and cart flows, and ongoing quality review across mobile journeys, catalog accuracy, and customer-facing interactions.
Evidence & scope: Working storefront, component and integration work, documented UI and catalog investigations, and iterative build checks. A complete live checkout regression suite and measured conversion outcomes are not claimed.
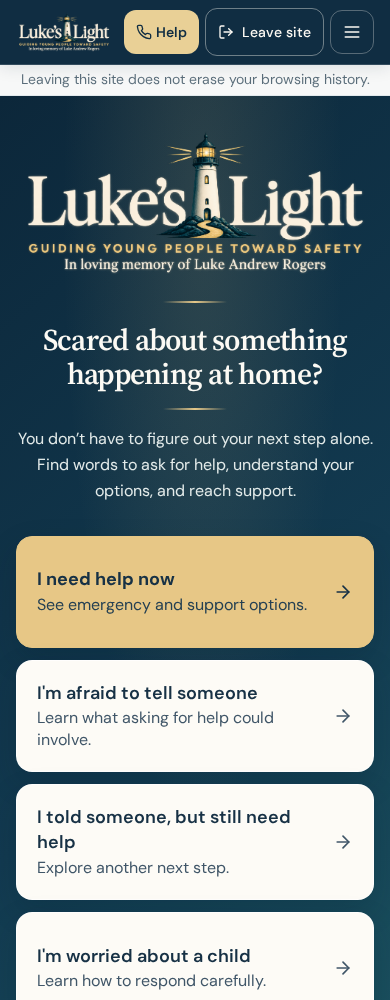
An independently developed digital resource platform created in memory of Luke Andrew Rogers, helping children, teens, and concerned adults navigate difficult situations and connect with established support services. Designed with a focus on accessibility, privacy awareness, responsible communication, and reliable user experiences.
Evidence & scope: React-based implementation, accessible interaction considerations, and safety-focused manual QA; no independent accessibility or clinical certification claimed.
HUMAN-CENTERED EVALUATION
I'm drawn to the ways business and technology intersect with psychology and human behavior—particularly how large language models learn, respond, and improve through human evaluation. Behind every AI interaction is a person who deserves technology they can trust. I believe meaningful innovation requires more than technical progress. It requires curiosity, critical thinking, and a commitment to truth, empathy, and accountability.
Check claims against authoritative sources; flag hallucinations and disclose uncertainty rather than filling gaps with confident guesses.
Look for exclusions, uneven treatment, and assumptions that may disadvantage users or misrepresent what they need.
Avoid exposing sensitive information and keep human review central when an answer is ambiguous, consequential, or potentially harmful.
This describes an independent quality-review philosophy, not a formal safety audit, regulatory assessment, or certification.
EVALUATION METHODS
Practical checks for model responses, training examples, and the workflows that deliver them.
Score outputs against factual accuracy, instruction following, tone and brand consistency, and schema adherence for JSON or other structured data.
Stress-test multi-step agent behavior with edge cases; classify hallucinations, prompt leakage, logic breaks, and behavioral drift, then document reproducible observations.
Review sample prompt–response pairs for source accuracy, consistent labels, and clear evaluation criteria. Extending this into a fine-tuning workflow is a development goal.
Compare expected and actual behavior across AI workflows, e-commerce journeys, and app integrations within the available test environment.
DEFINE → REVIEW → DOCUMENT → RECHECK
The same four-stage process applies to a product page, an AI-generated answer, or an entire customer journey. This is my working review framework—not an employer's proprietary standard.
Identify users, requirements, approved sources, important risks, edge cases, and acceptance criteria.
Compare actual behavior with expectations; check accuracy, instruction fit, consistency, usability, and unsupported claims.
Record steps, conditions, source evidence, expected versus actual behavior, category, impact, and severity.
Verify a change against the original issue and assess affected routes for regressions or new inconsistencies.
| Severity | Illustrative meaning |
|---|---|
| Critical | Severe safety, security, privacy, or system-integrity failure. |
| High | Material misinformation or a major workflow failure. |
| Medium | Significant functionality or content-quality issue. |
| Low | Minor formatting, style, or presentation issue. |
Illustrative criteria only. Severity depends on context, actual exposure, and the system's own risk model.
MY APPROACH
I start with the expected behavior, test what actually happens, and document any differences. I turn those observations into clear, actionable findings that teams can investigate, resolve, and retest.
Learn more about my workSet requirements, intended users, ground-truth sources, risks, and acceptance criteria.
Compare output and behavior with sources, instructions, edge cases, and real user needs.
Record conditions, expected versus actual results, impact, severity, and reproducible evidence.
Retest the original issue after changes, then check nearby behaviors for regressions.
EXPERIENCE
Ten years of hands-on web design and digital operations underpin my work in e-commerce QA, AI evaluation, publishing, and document quality.
Alignerr by Labelbox
Through qualification assessments and hands-on practice, I’ve developed familiarity with AI data annotation, labeling, and evaluation guidelines. I focus on accuracy, instruction-following, consistency, and the quality of human feedback used to improve AI outputs.
The Stop Trying Method
I manage editorial quality from manuscript through publication, performing manual checks for clarity, accuracy, consistency, formatting, and reader usability. I review print and digital proofs, correct defects, and refine content through careful revision.
Torch Republic Coffee Company
I oversee the storefront and test its customer experience, using manual QA to identify issues with product information, mobile layouts, navigation, carts, and Shopify integrations. I also evaluate AI-assisted content and workflows for accuracy, clarity, and consistency.
Self-employed contract support
I reviewed legal and supporting documents for accuracy, completeness, organization, and formatting. This detail-driven work strengthened my manual QA approach: checking facts against source records, catching inconsistencies, and documenting corrections with care.
Multiple Businesses & Organizations
For more than a decade, I’ve designed and maintained websites for multiple businesses and organizations. My hands-on QA work includes testing responsive layouts, navigation, usability, forms, and content accuracy, then troubleshooting defects and refining the experience.
CREDENTIALS
Amazon Web Services
Microsoft & LinkedIn
Kaggle
DeepLearning.AI
UiPath Academy
Atlassian University
EDUCATION
Minor in Business Administration
Texas A&M University–Corpus Christi
TECHNICAL SKILLS
TOOLS IN CONTEXT
Here’s where I’ve put my skills to work, along with the demonstration projects I’m building next.
Follow product discovery, navigation, cart entry points, content accuracy, responsive layouts, and the behavior users actually encounter.
Write expected behavior, compare synthetic responses against a source-of-truth catalog, classify failures, and keep evidence beside each result.
Maintain catalog content and site experiences, investigate broken routes or mobile controls, and recheck changes after updates.
Review synthetic fixtures and deterministic criteria, validate JSON request/response shapes, and organize result summaries.
Relevant next steps include repeatable data comparisons, integrity checks, and concise reporting scripts; not claimed as production deployments.
Target uses include repeatable browser flows and mobile viewport regressions. No finished automation suite is claimed here.
Target uses include request/response checks, invalid input, status codes, and API contracts. The current harness validates local contracts, not a live API.
Version history and clear defects support controlled changes; Jira triage and CI test pipelines are learning goals unless demonstrated by a linked artifact.
LET’S CONNECT
I’m interested in teams that value sound judgment, thoughtful testing, and clear documentation. If my work fits what you’re building, I’d be glad to talk.
Email Lisa Résumé and additional work samples available upon request by email.